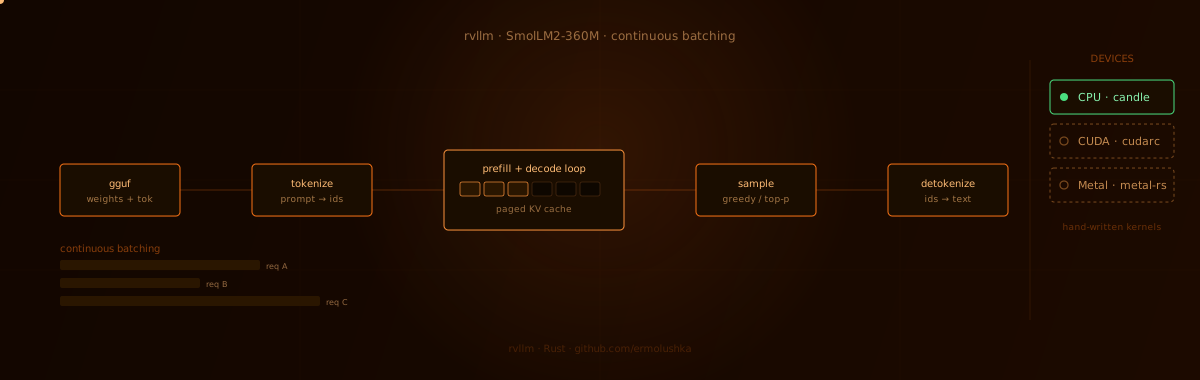
In the last post I described what rvllm does and never said how fast it is becuase I didn’t profile and measure it effectively. When I finally did, a 360M parameter model on an M5 MacBook was producing 0.9 tokens per second. A prompt of 128 tokens took over 7 seconds before the first word came out.
It got worse with more requests. Four requests at once ran at 0.3 tokens per second in total, which is slower than one request alone. Continuous batching is the whole point of this project, so that one bothered me.
This post is about finding out why. The short version is that the math was almost free and I was copying memory.
Measuring first
I use the bench binary that comes with rvllm. Every number below is SmolLM2-360M (Q8_0 file, dequantized to F32 on load), a 128 token prompt, 16 generated tokens, greedy decoding, on an M5 MacBook Pro.
Before changing anything I added a few things to it: time to first token, prefill speed and decode time per step reported separately, and a checksum of every generated token. The checksum matters more than it sounds. Greedy decoding is deterministic, so if I speed something up and the checksum changes, I either broke something or changed the numerics in a way I have to explain. It stayed the same after every change in this post.
The starting point:
batch=1   first token 7.1 s    decode 619 ms per token    0.9 tok/s   2.6 GB
batch=4   first token 34.6 s   decode 3557 ms per step    0.3 tok/s   5.1 GB
The KV cache write was copying the whole cache
The first thing I fixed was writing new keys and values into the cache. I was using candle’s slice_assign, and I assumed I put it in place. It allocates a new tensor the size of the whole layer’s cache and copies everything, with your slice patched in. I was doing that for every token, every layer, for both K and V.
That also explains why batching made things worse. The bench sizes the block pool for a full context per sequence, so four requests means a cache four times bigger, and each token write copies four times as much.
The fix is slice_set, which does write in place, plus grouping consecutive tokens that land in the same block into one write. One trap here: my KvStorage derived Clone, and cloning a candle tensor only bumps a refcount. With in-place writes, a clone would silently share the cache with the original. My batched-versus-unbatched test clones the cache to compare the two paths, so it would have compared a cache with itself. I wrote a Clone that deep copies, and a test for it.
While I was in there I changed three other things for prefill. I only compute logits for the last prompt token (the output layer is a 49152 by 960 matmul and I was running it for all 128 rows to use one of them), and I build the RoPE tables and the attention mask once per forward pass instead of once per head per layer.
TTS went from 7.1 seconds to about 0.37. I changed four things at once, so I can’t tell you how much each one gave. My bet is the cache write, since the batch=4 decode step also dropped a lot (3557 ms to 2156 ms) and that number scales with cache size.
But batch=1 decode had barely moved. 619 ms became 557 ms.
The profiler said it wasn’t math
That number made no sense. The model is 360M parameters in F32, about 1.4 GB. Reading all of it once per token on this machine should take tens of milliseconds, not more than half a second.
Instead of guessing more I ran macOS’s built-in sample on the process while it was decoding:
main thread, ~6700 samples
  6459  candle_core::storage::Storage::copy_strided_src
   243  gemm_f32::gemm::f32::neon::gemm_basic
96 percent of the time was one copy function, and 3.6 percent was the actual matrix multiplication. The call stack under it went swiglu_ffn, then Tensor::broadcast_matmul, then Tensor::contiguous.
My weights are stored as [out, in], so every linear layer computes x.broadcast_matmul(&weight.t()). When x is a 3D batch and the weight is 2D, broadcast_matmul broadcasts the weight across the batch and then calls .contiguous() on it. That builds a fresh, transposed, contiguous copy of the whole weight matrix. Every layer, every matmul, and the giant output layer too, on every token. Over a gigabyte of copying to save a few milliseconds of arithmetic.
Prefill was fine because it ran with 2D tensors, where nothing needs broadcasting, and plain matmul reads a transposed view through strides without copying anything. Only the batched path had the problem, and decode always goes through the batched path.
The fix is small. Flatten the leading dimensions into one, do a normal 2D matmul on the transposed view, and reshape back:
pub fn linear(x: &Tensor, weight: &Tensor) -> Result<Tensor> {
    let dims = x.dims();
    let in_features = x.dim(D::Minus1)?;
    let rows: usize = dims[..dims.len() - 1].iter().product();
    let mut out_dims = dims.to_vec();
    *out_dims.last_mut().unwrap() = weight.dim(0)?;
    x.reshape((rows, in_features))?
        .matmul(&weight.t()?)?
        .reshape(out_dims)
}
Decode went from 557 ms to 33 ms per token. Same checksum. Peak memory dropped too, since those copies were allocations that had to live somewhere.
After
                 before          after
batch=1  first   7.1 s           0.3 to 0.5 s
         decode  619 ms          33 ms per token
         total   0.9 tok/s       16.0 tok/s
         memory  2.6 GB          2.0 GB

batch=4  first   34.6 s          0.33 s
         decode  3557 ms         66 ms per step
         total   0.3 tok/s       26.9 tok/s
         memory  5.1 GB          3.1 GB
The first token times move around by a hundred milliseconds or so between runs, since prefill is short. The decode numbers were stable.
Batching now does what it’s supposed to. Four requests together give 27 tokens per second in total against 16 for one, and a step takes 2 times longer for 4 times the work.
The rest was cleanup
After the speed problems were gone I spent a while on the structure of the code. There were two complete forward paths, one for a single sequence and one for a batch, doing the same thing. Prefill is just a batch of one, so I deleted the single path, a couple hundred lines. Weights now live in a Model with a Vec<Layer> instead of a hashmap looked up by strings like blk.7.attn_q.weight on every pass, and a missing key in the GGUF file is an error instead of a silent zero. Grouped-query attention no longer copies K and V three times per layer to line the heads up. Top-p sampling no longer sorts all 49152 logits for every token.
None of that changed decode speed in any way I could measure. What it bought was less code, and about 0.3 GB less peak memory, partly because the model no longer dequantizes the embedding matrix twice when input and output embeddings are tied.
One more thing worth saying: I turned on fat LTO in the release profile back when decode was 96 percent memcpy and couldn’t tell whether it helped. Once the copying was gone the difference was obvious, 33 ms against 46 to 49 ms without it, in three runs of each, alternating.
And a small embarrassing one. While reading the scheduler crate I noticed rvllm was still pinned to version 0.1.0 of kv-cache-scheduler, which doesn’t have a prefix cache fix I had already made upstream. Published crate, local fix, never bumped. It’s on 0.2.0 now.
So, what’s up?
This isn’t a comparison with llama.cpp, and I wouldn’t read it as one. I haven’t run llama.cpp on the same file yet. There’s also an obvious reason not to expect parity: the weights are stored as 8-bit but I multiply them as F32, so every token moves four times more bytes than it needs to.
If there’s a lesson it’s the boring one: I should have profiled before touching anything. I’d also check what your tensor library copies before trusting it, because slice_assign and broadcast_matmul both look cheap and neither is. And keep a checksum of the output around, so every speedup comes with proof that the model still says the same thing.
The GPU work is next, and I’m glad I’ll start it from a CPU version that isn’t secretly a memcpy benchmark. The code is at github.com/ermolushka/rvllm.